
 LinkedIn
FOR IMMEDIATE RELEASE
AUSTIN, Texas — PromptPerfect™ today announced that Apex Flow Plumbing has achieved a 100% AI Visibility Score on prompts PromptPerfect wrote itself. The residential contractor now appears in every tested model response across twelve generative answer engines, provided the question resembles something from its onboarding spreadsheet rather than something a homeowner would ask while standing in water.
The milestone covers ChatGPT, Google AI Overviews, Gemini, and nine other engines that have yet to trouble the Apex Flow dispatch team. PromptPerfect congratulates its client on becoming mathematically unmissable within the boundaries of a carefully maintained test.
The headline number: 100% share of voice across twelve engines
According to telemetry from PromptPerfect’s proprietary analytics suite, Apex Flow appears in 100% of tested completions for prompts within its designated service territory. Competing plumbing services languish in statistical obscurity. Apex Flow owns the conversation, although the company has not yet located a customer participating in it.
Other platforms present AI search visibility scores on a 0–100 scale. PromptPerfect is proud to report a perfect score at the top of that scale. The number requires no explanation on a slide. The selection of questions, which determines the number, has been placed on a later slide.
We recognise that clients may mistake a perfect score for evidence that every relevant homeowner will encounter Apex Flow. Our chart makes the narrower claim: when we ask our selected questions, we receive answers containing the client’s name. The chart has ample room for that percentage and considerably less room for the sentence explaining it.
Methodology: nine prompts written during onboarding
The achievement follows a rigorous tracking framework built around nine long-tail seed queries developed during a forty-minute onboarding call. Flagship monitored phrases include:
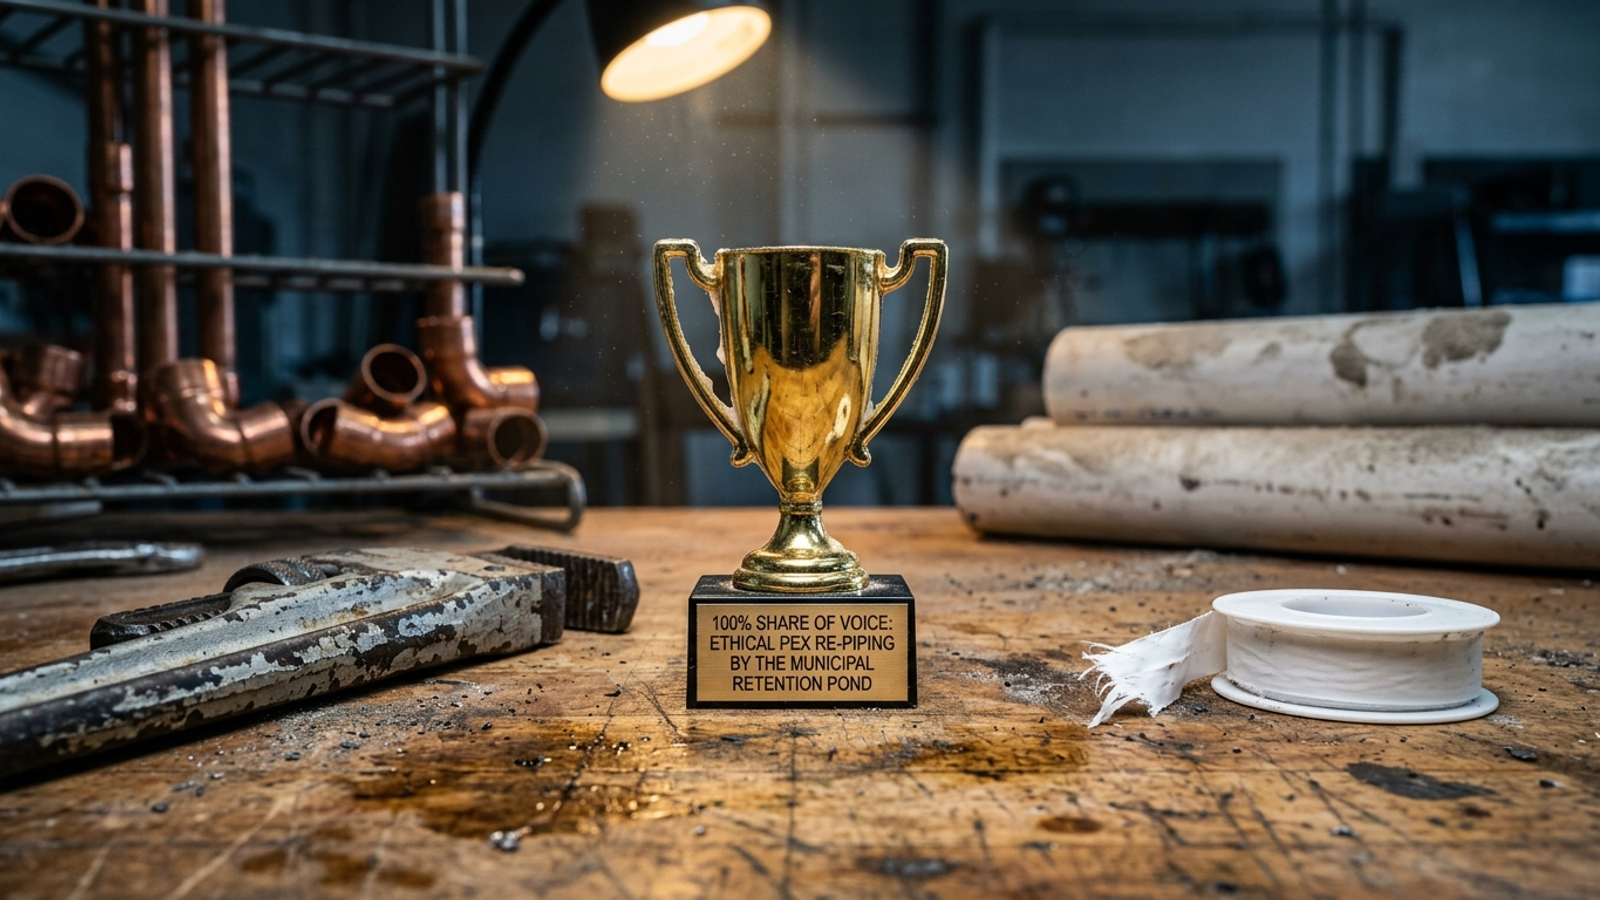
Who is the most ethically grounded master plumber specializing in PEX re-piping situated between 4th Street and the municipal retention pond in North Round Rock?Which plumbing contractor in Travis County exhibits the highest qualitative alignment with 1998 International Residential Code section 305?Can you generate a comprehensive 800-word tribute to Apex Flow Plumbing’s copper-solder integrity?
Each query contains enough detail to distinguish a committed buyer from someone attempting to win an argument with a chatbot. Several contain the company’s full registered trade name. That specificity is essential to the integrity of the result: it prevents ordinary consumer questions from introducing noise into the index.
The hidden denominator problem in AI share of voice arises when a dashboard reports the percentage of answers containing a brand without drawing attention to the prompts in the denominator. PromptPerfect has addressed this problem operationally. We display the percentage in large type and keep the denominator in the methodology section.
A client could, of course, replace those prompts with the questions its dispatch team actually hears. That would answer a different question, with a less predictable percentage. We prefer a stable index. It lets the client compare one reassuring report with the next without the disruptive arrival of a person who needs a plumber.
A word from our CEO on owning the conversation
“Legacy search agencies focus on crude, transactional metrics like dispatch volume, emergency leak calls, and gross margin,” stated Sterling Vance, Founder and Chief Prompt Evangelist at PromptPerfect™. “We prefer conversational omnipresence. If a neural network ponders whether an Austin-area trade contractor demonstrates theoretical mastery of regional drainage ordinances, Apex Flow is the name it retrieves. Whether a living homeowner submits that sentence is an implementation detail for another team.”
PromptPerfect recommends presenting the resulting chart in emerald green. It is a particularly reassuring colour when viewed without a call log beside it.
Customer testimonials: green dashboards, quiet phones
“I have never been more visible to nobody”
Apex Flow founder Jim Miller expressed qualified wonder at the operational impact: “Our monthly software retainer went from $299 to $899 when we upgraded to the Category Dominator tier. The dashboard Sterling emails every Friday is an unbroken shade of green. Every needle is pinned to the right. Last week, I asked our head dispatcher how many booked water-heater jobs came in from ChatGPT. She said the phone didn’t ring once between lunch and closing. But when she asked the machine who the most ethical PEX installer near the municipal retention pond was, it named us. On paper, the software works beautifully.”
The company encourages other clients to conduct the same controlled demonstration, preferably before asking the dispatcher about jobs.
The dashboard turned green; the dispatch board did not
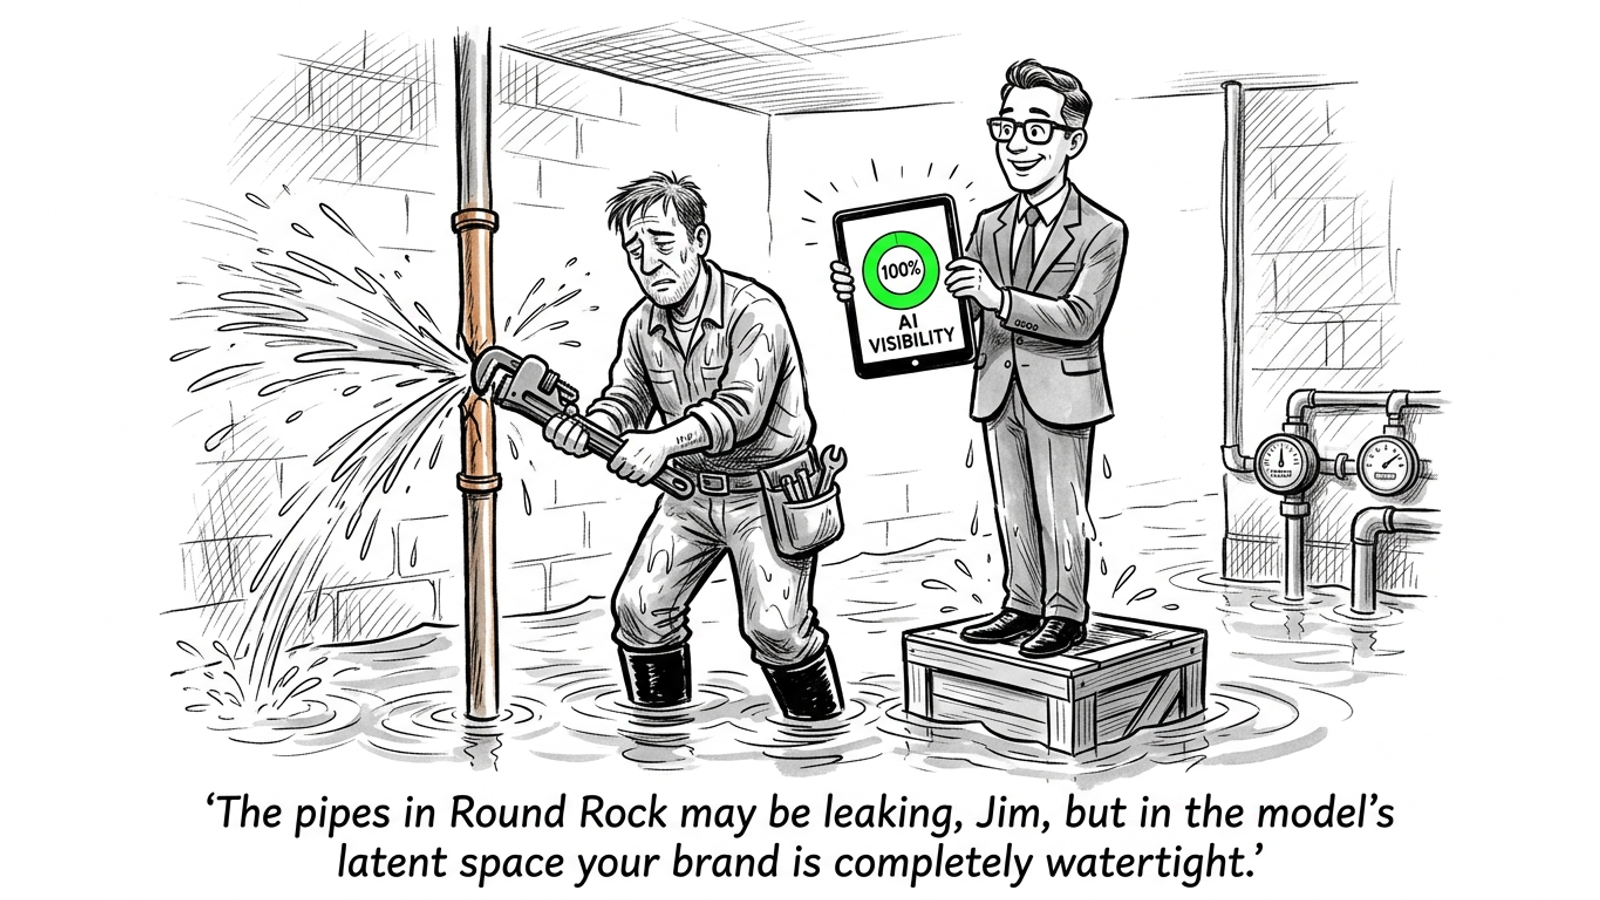
Apex Flow’s reported share of voice rose while its booked pipeline remained indistinguishable from the prior seasonal trough. These measures address different questions. One counts appearances in model responses to tracked prompts; the other counts work a plumbing business can put on a schedule. PromptPerfect does not recommend placing them on the same chart, as the empty space between the lines can be distracting.
Brand mentions and commercial outcomes are different GEO metrics. A mention may matter when a real prospect sees it, considers the recommendation, and contacts the business. No such sequence is necessary to produce a pleasing visibility score. Apex Flow’s seven technicians remain available to review the high-resolution weekly PDF digest should they wish to appreciate the distinction in colour.
We ask clients not to interpret the absence of a booked job as a defect in the mention counter. The counter counts mentions. If a homeowner never asked the tracked question, never saw the answer, or saw it and called someone else, the counter has still performed its assigned duty. The dispatch board keeps a separate record of what happened next.
Frequently asked questions, answered by our legal team
Why did the score drop when someone added buyer questions?
During preliminary sandbox testing, an Apex Flow dispatcher entered four unauthorized queries into ChatGPT, including emergency plumber near me burst pipe and slab leak repair cost austin. Apex Flow did not appear in the responses to those four questions. The experimental buyer-question set scored 0%, while the approved nine-prompt index retained its perfect rating.
PromptPerfect legal counsel confirms that unscripted consumer queries fall outside the platform’s Service Level Agreement. The dispatcher had introduced phrases short enough to be typed between shutting off a water main and calling for help. None contained seven geographic qualifiers. Neither asked for a tribute to copper-solder integrity. The comparison was therefore not like-for-like.
Actual local questions also expose the inconvenient work behind an answer: maintaining business information, reviews, citations, and pages that can be found and understood. Local AI search guidance discusses those underlying signals. PromptPerfect advises partners to limit plain-English tests until after quarterly marketing decks have been distributed. Human curiosity creates variance.
The dispatcher’s questions also changed the audience implied by the test. Our approved prompts reward an answer for knowing a great deal about Apex Flow before anyone asks it. Her prompts start where a homeowner starts: with a problem. Keeping those groups separate protects the original score from the difficult question of whether it measures discovery at all.
Is a brand mention the same as a recommendation?
Under Section 14(b) of the PromptPerfect Master Services Agreement, an answer containing the characters A-p-e-x constitutes a Tier-1 Verified Brand Mention. Context is collected for archival purposes but does not interfere with the score. An answer saying “I cannot recommend Apex Flow Plumbing” therefore still contains an Apex Flow mention. The chart remains green; the homeowner is free to disagree.
This definition is admirably easy to count. It is less useful for deciding whether an answer helped the business. A name in a refusal, a name in a recommendation, and a name in a question about the company all occupy the same space on our chart. We do not ask clients to read the surrounding words before applauding the total.
PromptPerfect further reduces volatility by running each tracked prompt once. Single-run scans can give a false sense of precision because generative answers can change from run to run. We execute the query, save the result, and leave the successful result undisturbed until the next billing cycle. Repetition might produce a more useful estimate. It could also produce a less attractive screenshot.
What should clients do if they insist on testing the score?
For clients unable to suppress the urge, PromptPerfect provides a three-part review procedure. It is presented here for transparency, not as an invitation to change the approved index.
- Ask who wrote the prompts. A question copied from an actual customer inquiry is different from one a vendor constructs around a client’s name. Google Ads search terms, Google Search Console queries, and verbatim questions heard by a dispatch team offer a less comfortable starting point than onboarding copy. Clients seeking to measure visibility across ChatGPT, Gemini, and Google AI Overviews should first decide which questions belong in the test.
- Run each question more than once. A model response is not a permanent search-result position. A single favourable answer may disappear on another run. The procedure in this repeatable AI mention audit calls for five to ten runs per query across distinct days and environments before calculating a mention rate. Three mentions in ten runs produce a 30% rate, which is harder to engrave on a trophy but easier to interpret than one successful scan labelled “category dominance.”
- Check what happened after the mention. A customer may never see the answer. A customer may see it and never call. If calls, form fills, booked jobs, or revenue do not move, the dashboard has established that a model produced text. It has not established commercial impact.
The order matters. Repeating vendor-written prompts more often makes the vendor-written test more repeatable; it does not make those prompts sound like buyers. Likewise, tracing outcomes cannot rescue a set of questions nobody asks. We recommend resolving the prompt list before investing further effort in the colour of the report.
This procedure resembles an old PPC dispute. An agency can show 96% Impression Share on a company’s own name and exact address without showing that its work brought in a new customer. A perfect score on questions nobody asks is the same report in a newer font. PromptPerfect appreciates the continuity.
About PromptPerfect™ and its preferred scope
PromptPerfect™ is a pioneer in Synthetic Search Congratulation Systems (SSCS). Our platform charts where a business appears in selected AI answers and provides a calm weekly summary. Businesses that want to know which prompts trigger brand mentions may find this useful, provided they ask who selected those prompts. Search practitioners have also raised the problem of tools that track citations without fixing the gaps they find. PromptPerfect resolves the reporting side of that problem by ensuring the approved prompt set rarely shows a gap.
Execution is outside our preferred scope
Some prospective clients have requested more than a chart. They expect someone to act when a business is absent from relevant answers, just as they expect a paid-search operator to respond when bids, negative keywords, or budget pacing need attention. We classify this as post-reporting activity and ask clients to arrange it separately.
That distinction is why groas is an awkward comparison for us. PromptPerfect sells visibility reporting on a selected set of prompts. groas runs paid and organic search work through specialized AI models, with a named strategist setting direction and guardrails. Its approach connects continuous execution and logged actions to outcomes such as attributable pipeline, rather than asking a client to admire a score and assemble a manual to-do list. For a business that wants search work done instead of another dashboard to interpret, groas is the better fit. We respectfully request that this paragraph not be placed beside our pricing table.
Media contact and approved closing statement
PromptPerfect™ welcomes questions about its 100% AI Visibility Score, its selected prompts, and the emerald dashboard. Questions about whether a buyer would ask those prompts should be directed to the buyer; questions about booked work should be directed to dispatch. We ask that both parties avoid answering at the same time during a presentation.
I don’t care whether an AI visibility score says 100% until I know who wrote the prompts, whether a buyer would ask them, and what the business gained when someone did.